An aggregated feed of all of my posts
I am working on a project to create a small system monitoring dashboard using the python psutil library.
The repo is here (if you want actual system monitoring please use netdata).
I’m using streamlit and plotly for the webserver, design, and plotting at the moment.
My Use Case #
I needed a way to refresh my plotly charts with a fixed window of time so that I’m able to just see relevant recent data instead of cramming all data for all time into one plot that’s 500 pixels wide…
Checking the length of arrays or lists every time I get a new piece of data feels kind of dumb and I thought “python must have a way to do this”…
“This” meaning, update values in a fixed length array without reallocating memory or recreating a copy of the list
Deques #
Enter the deque.
It means “double ended queue” and is in general an Iterable that you can append values to either side or pop values from either side.
The init signature is straightforward enough and I’m sure there’s more to them than I know yet but here’s how I use it…
from collections import deque
my_deque = deque([1,2,3])
This gives us my_deque, created from an iterable, with several familiar methods like index, extend, append, etc.
However there’s some new ones too such as appendleft and popleft.
my_deque.appendleft('a')
print(my_dequqe)
>>> deque(['a', 1, 2, 3])
my_deque.popleft()
>>> 'a'
<!--markata-attribution-->
print(my_deque)
>>> deque([1, 2, 3])
These are handy ways to manipulate the iterable that I needed for the arrays I plot with plotly!
See my follow-up to this on using Deques with plotly and streamlit to create a quick “dashboard” with live streaming data!
Plotly-And-Streamlit
Starship
self-hosted-media
EDA #
I work with data a lot, but the nature of my job isn’t to dive super deep into a small amount of datasets, I’m often jumping between several projects every day and need to just get a super quick glance at some tables to get a high level view.
When I’m doing more interactive exploration I’ve graduated from Jupyter cells with df_N.head() to using an amazing tool called visidata
However, Visidata is a terminal based application and I’m often in an iPython console… so is there a way to move even faster for my super quick summary views?
yes!
Skimpy #
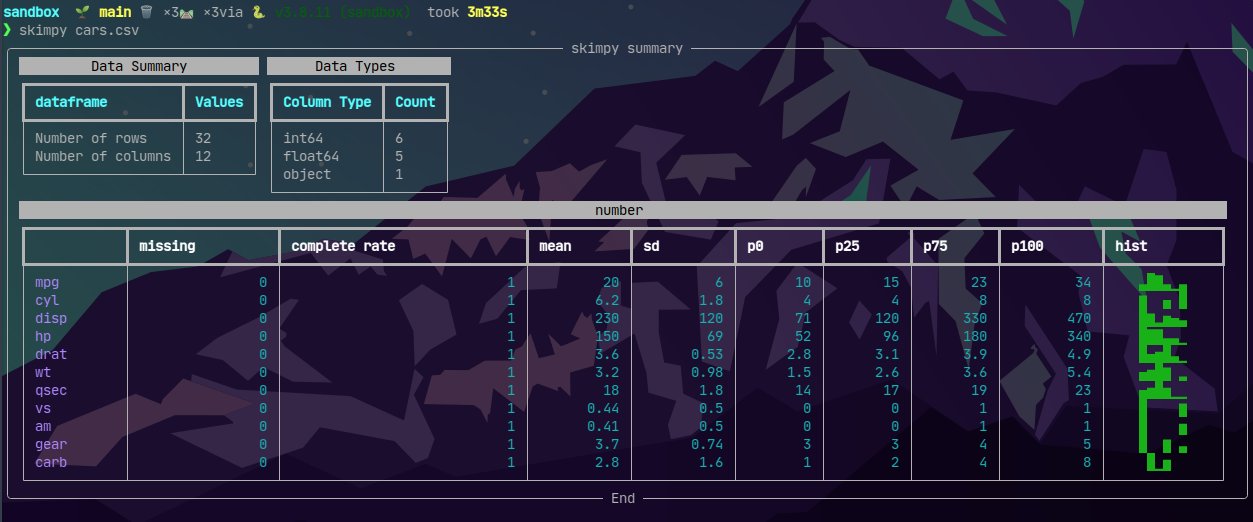
First thing to do is pip install skimpy and then it’s as easy to get some summary stats with skimpy <data>
This is super nice for seeing missing values in particular as well as the distribution shape of the data.
iPython #
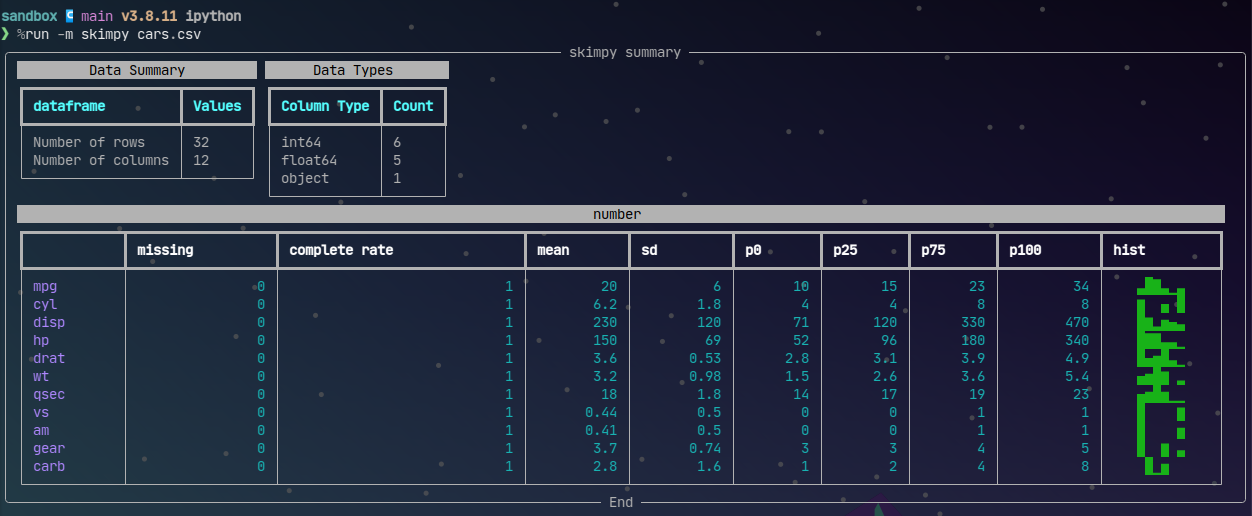
But wait… I just said I’m normally in an iPython session but that was called from zsh.. If I’m hoping back into zsh I might as well use visidata to have more powerful exploration at my fingertips. So… can I see this table quickly without breaking my iPython workflow?
Of course you can with magic!
The above assumes you’re looking at a file, like you would in the terminal.
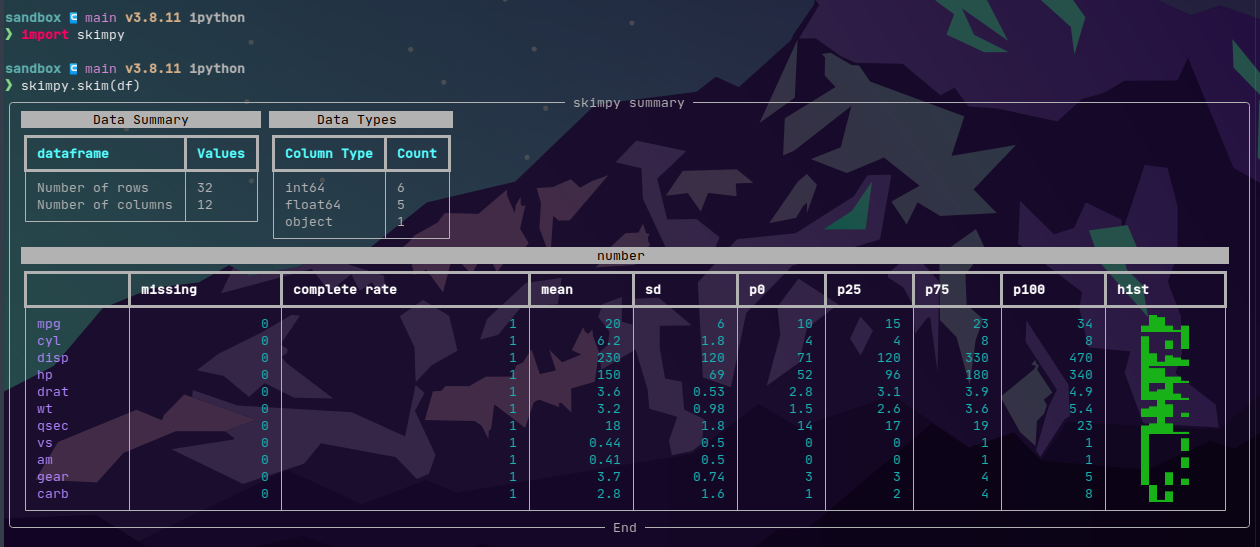
skimpy works even better in iPython with from skimpy import skim then pass any DataFrame to skim!
Truenas-And-Wireguard
I like to keep my workspace clean and one thing that I don’t personally love looking at is the __pycache__ directory that pops up after running some code.
The *.pyc files that show up there are python bytecode and they are cached to make subsequent runs a tad faster.
My stuff never really needs this bonus speed boost and so I came across a neat tool called pyclean!
Pyclean #
The easiest way (in my opinion) to run pyclean is to just use pipx run.
sandbox/src 🌱 main 🗑️ ×3🛤️ ×2via 🐍 v3.8.11 (sandbox) took 9s
❯ ls
abcmeta.py __pycache__ python-print-align.py system-monitor-psutils.py
sandbox/src 🌱 main 🗑️ ×3🛤️ ×2via 🐍 v3.8.11 (sandbox)
❯ pipx run pyclean .
⚠️ pyclean is already on your PATH and installed at /usr/bin/pyclean. Downloading and running anyway.
Cleaning directory .
Total 1 files, 1 directories removed.
sandbox/src 🌱 main 🗑️ ×3🛤️ ×2via 🐍 v3.8.11 (sandbox)
❯ ls
abcmeta.py python-print-align.py system-monitor-psutils.py
Why not bash? #
You could accomplish something similar with rm **/*.pyc or find -n '*.py?' -delete but there’s a chance you’ll find something you don’t love gone.
Also this won’t help our poor Windows friends out there!
pyclean is fully python so it’s OS independent.
Credits! #
Mike Driscoll has been posting some awesome posts about psutil lately.
I’m interested in making my own system monitoring dashboard now using this library.
I don’t expect it to compete with Netdata or Glances but it’ll just be for fun to see how Python can solve this problem!
Repo coming soon
Example code: #
Here’s a short snippit to get used/available/total RAM and disk space (on partitions that you probably care about)
import psutil
import socket
print(f"System Memory used: {psutil.virtual_memory().used // (1024 ** 3)} GB")
print(f"System Memory available: {psutil.virtual_memory().available // (1024 ** 3)} GB")
print(f"System Memory total: {psutil.virtual_memory().total // (1024 ** 3)} GB")
print(f"Hostname: {socket.gethostname()}")
partitions = psutil.disk_partitions()
for part in partitions:
mnt = part.mountpoint
if "snap" in mnt or "boot" in mnt:
continue
disk = psutil.disk_usage(mnt)
print(f"Usage at {mnt} on {part.device}: {disk.used // (1024 ** 3)} GB")
print(f"Free at {mnt} on {part.device}: {disk.free // (1024 ** 3)}GB")
print(f"Total at {mnt} on {part.device}: {disk.total // (1024 ** 3)}GB")
Bonus Ipython tip! Save this to a script called my_script.py and in Ipython you can %run -m my_script to run it!
project ↪ main v3.8.11 ipython
❯ %run -m system-monitor-psutils
System Memory used: 25 GB
System Memory available: 5 GB
System Memory total: 31 GB
Hostname: ryzen-3600x
Usage at / on /dev/nvme1n1p2: 81 GB
Free at / on /dev/nvme1n1p2: 351 GB
Total at / on /dev/nvme1n1p2: 456 GB
If you work with a template for several projects then you might sometimes need to do the same action across all repos.
A good example of this is updating a package in requirements.txt in every project, or refactoring a common module.
If you have several repos to do this across then it can be time consuming… enter mu-repo
Mu #
mu-repo is an awesome cli tool for working with multiple git repositories at the same time. There are several things you can do:
mu statuswill give you thegit statusof every registered repo (see below)mu shwill let you execute system level commands in every repomu stashwill stash all changes across all registered repos- There’s literally a ton more but these are some handy ones
Registration #
mu tracks its own groups, and there is a default group when no particular one is active.
It’s as simple as mu register proj1 prog2 ... to get repos registered
❯ mu register proj1 proj2
Repository: proj1 registered
Repository: proj2 registered
❯ mu status
proj1 : git status
On branch main
No commits yet
Untracked files:
(use "git add <file>..." to include in what will be committed)
requirements.txt
nothing added to commit but untracked files present (use "git add" to track)
proj2 : git status
On branch main
No commits yet
Changes to be committed:
(use "git rm --cached <file>..." to unstage)
new file: requirements.txt
Working with mu #
As you can see above I have two projects each with a requirements.txt added but not committed yet.
Using mu I can stage this change across both repos at once.
❯ mu add requirements.txt
proj1 : git add requirements.txt
proj2 : git add requirements.txt
Then as you might imagine, I can make the commit in each repo
❯ mu commit -m "Add requirements.txts"
proj1 : git commit -m Add requirements.txts
[main (root-commit) 18376d7] Add requirements.txts
1 file changed, 1 insertion(+)
create mode 100644 requirements.txt
proj2 : git commit -m Add requirements.txts
[main (root-commit) 18376d7] Add requirements.txts
1 file changed, 1 insertion(+)
create mode 100644 requirements.txt
mu groups #
The other thing I got a lot of use out of recently was mu’s groups.
At work I have about 40 repos cloned that are all based on the same kedro pipeline template.
Some of these projects have been deprecated.
I also have several more repos that are not kedro template - custom libraries or something.
group let me utilize mu across different groups of repos.
Say proj2 is a deprecated project that I don’t need to worry about making changes to anymore.
I don’t just have to unregister it, instead I can make a group called “active” and register proj1 in that group
❯ mu group add active --empty
~/personal
❯ mu group add deprecated --empty
~/personal
❯ mu group
active
* deprecated
The * tells me which group is active.
The --empty flag tells mu to not add all registered repos to that group.
If I don’t want to use any groups then mu group reset will go back to the default group with all registered repos.
With groups I can register only the repos that I want to be working across in their own group and not worry about affecting other repos with my batch changes!