An aggregated feed of all of my posts

616 posts latest post 2026-10-06
Publishing rhythm
Jun 2026 | 3 posts

man can be a pain to read… and there’s lots of alternatives out there and one I’ve just started playing with is cheat

man man will give you this plus a billion more lines of docs, which is useful when you need it…

MAN(1)                                                                                                                       Manual pager utils                                                                                                                      MAN(1)

NAME
       man - an interface to the on-line reference manuals

SYNOPSIS
       man  [-C  file]  [-d] [-D] [--warnings[=warnings]] [-R encoding] [-L locale] [-m system[,...]] [-M path] [-S list] [-e extension] [-i|-I] [--regex|--wildcard] [--names-only] [-a] [-u] [--no-subpages] [-P pager] [-r prompt] [-7] [-E encoding] [--no-hyphenation]
       [--no-justification] [-p string] [-t] [-T[device]] [-H[browser]] [-X[dpi]] [-Z] [[section] page[.section] ...] ...
       man -k [apropos options] regexp ...
       man -K [-w|-W] [-S list] [-i|-I] [--regex] [section] term ...
       man -f [whatis options] page ...
       man -l [-C file] [-d] [-D] [--warnings[=warnings]] [-R encoding] [-L locale] [-P pager] [-r prompt] [-7] [-E encoding] [-p string] [-t] [-T[device]] [-H[browser]] [-X[dpi]] [-Z] file ...
       man -w|-W [-C file] [-d] [-D] page ...
       man -c [-C file] [-d] [-D] page ...
       man [-?V]

DESCRIPTION
       man is the system's manual pager.  Each page argument given to man is normally the name of a program, utility or function.  The manual page associated with each of these arguments is then found and displayed.  A section, if provided, will direct  man  to  look
       only  in  that  section of the manual.  The default action is to search in all of the available sections following a pre-defined order ("1 n l 8 3 2 3posix 3pm 3perl 3am 5 4 9 6 7" by default, unless overridden by the SECTION directive in /etc/manpath.config),
       and to show only the first page found, even if page exists in several sections.

       The table below shows the section numbers of the manual followed by the types of pages they contain.

       1   Executable programs or shell commands
       2   System calls (functions provided by the kernel)
       3   Library calls (functions within program libraries)
       4   Special files (usually found in /dev)
       5   File formats and conventions eg /etc/passwd
       6   Games
       7   Miscellaneous (including macro packages and conventions), e.g. man(7), groff(7)
       8   System administration commands (usually only for root)
       9   Kernel routines [Non standard]

       A manual page consists of several sections.

       Conventional section names include NAME, SYNOPSIS, CONFIGURATION, DESCRIPTION, OPTIONS, EXIT STATUS, RETURN VALUE, ERRORS, ENVIRONMENT, FILES, VERSIONS, CONFORMING TO, NOTES, BUGS, EXAMPLE, AUTHORS, and SEE ALSO.

       The following conventions apply to the SYNOPSIS section and can be used as a guide in other sections.

       bold text          type exactly as shown.
       italic text        replace with appropriate argument.
       [-abc]             any or all arguments within [ ] are optional.
       -a|-b              options delimited by | cannot be used together.
       argument ...       argument is repeatable.
       [expression] ...   entire expression within [ ] is repeatable.

       Exact rendering may vary depending on the output device.  For instance, man will usually not be able to render italics when running in a terminal, and will typically use underlined or coloured text instead.

       The command or function illustration is a pattern that should match all possible invocations.  In some cases it is advisable to illustrate several exclusive invocations as is shown in the SYNOPSIS section of this manual page.

EXAMPLES
       man ls
           Display the manual page for the item (program) ls.

       man man.7
           Display the manual page for macro package man from section 7.

But what if you don’t? #

cheat man

# To convert a man page to pdf:
man -t bash | ps2pdf - bash.pdf

# To view the ascii chart:
man 7 ascii

You get tiny examples to remind you of what you probably are trying to do!
I got into a pickle where I encrypted the ssh keys I use for my SSH connections on LAN, but then I couldn’t run my ansible playbook on my server! ssh-keygen -p and leave the new passphrase blank saved my day (although password protected key files are safer!)

TL;DR - just reset it to nothing

ssh-keygen -p will let you reset the passphrase on your ssh keys (good for you! yay security!)

But I needed to remove the passphrase to quickly deploy an ansible playbook 🤓

Mike Driscoll recently tweeted about making colored out with pandas DataFrames and I just had to try it for myself

Use Case

First though… why? My biggest use case is a monitoring pipeline of mine… The details aside, the output of my pipeline is a dataframe where each row has information about a failed pipeline that I need to go look into. I dump that result to a simle html file that’s hosted on an internal site and the file is updated every couple of hours. Adding some colored indicators automatically to the rows to help me assess severity of each record would be a handy way to quickly get an understanding the state of our pipelines.

How?

The docs for the applymap method state simply:

Apply a CSS-styling function elementwise.

Updates the HTML representation with the result.

So we can write a function that returns color: {color} based on the dataframe values and when we drop that dataframe to html we’ll have some simple css styling applied automagically!

By default the function will be applied to all columns of the dataframe, but that’s not useful if the columns are different types which is usually the case. Luckily there is a subset keyword to only apply to the columns you need!

Consider my example

sandbox   main via 3.8.11(sandbox) ipython
❯ df = pd.read_csv("cars.csv")

sandbox   main via 3.8.11(sandbox) ipython
❯ def mpg_color(val: float):
...:     color = "red" if val < 21 else "green"
...:     return f"color: {color}"

sandbox   main via 3.8.11(sandbox) ipython
❯ df.style.applymap(mpg_color, subset="mpg").to_html("color.html")

I want to quickly see if the mpg is any good for the cars in the cars dataset and I’ll define “good” as better than 21 mpg (not great I know but just for the sake of discussion…)

The function returns an appropriate css string and after I style.applymap on just the mpg column we get this!

  Unnamed: 0 mpg cyl disp hp drat wt qsec vs am gear carb
0 Mazda RX4 21.000000 6 160.000000 110 3.900000 2.620000 16.460000 0 1 4 4
1 Mazda RX4 Wag 21.000000 6 160.000000 110 3.900000 2.875000 17.020000 0 1 4 4
2 Datsun 710 22.800000 4 108.000000 93 3.850000 2.320000 18.610000 1 1 4 1
3 Hornet 4 Drive 21.400000 6 258.000000 110 3.080000 3.215000 19.440000 1 0 3 1
4 Hornet Sportabout 18.700000 8 360.000000 175 3.150000 3.440000 17.020000 0 0 3 2
email1@me.com
somebody_else@gmail.com

#! /bin/bash
# pick multiple emails from list and combine into comma seperated array
emails=`cat .../emails | fzf -m | sed 's/^\|$/"/g'|paste -sd,` 

echo $emails

My Nextcloud woes

I wrote here about setting up www-data as the owner of any directories you want nextcloud to manage. However, I regularly struggle wtih permissions issues on my NAS because of the external storage app anyways so I’ve decided to just put our photos in the spot Nextcloud would otherwise put them, and use this as healthy pressure on our family to organize our photos and put the ones we care about with the rest of our family media.

Migration

Because I had a ton of photos on the NAS anyways that I wanted moved over to Nextcloud I just rsync’d the photos directory on my NAS to the user’s photos directory in nextcloud but they weren’t showing up in the web UI!

The Fix?

As www-data I needed to php /var/www/nextcloud/occ files:scan --all inside my nextcloud docker container AFTER moving a bunch of photos off my “NAS” into the folder mounted to the nextcloud container as its data folder! Before I did this they weren’t showing up in the web UI/

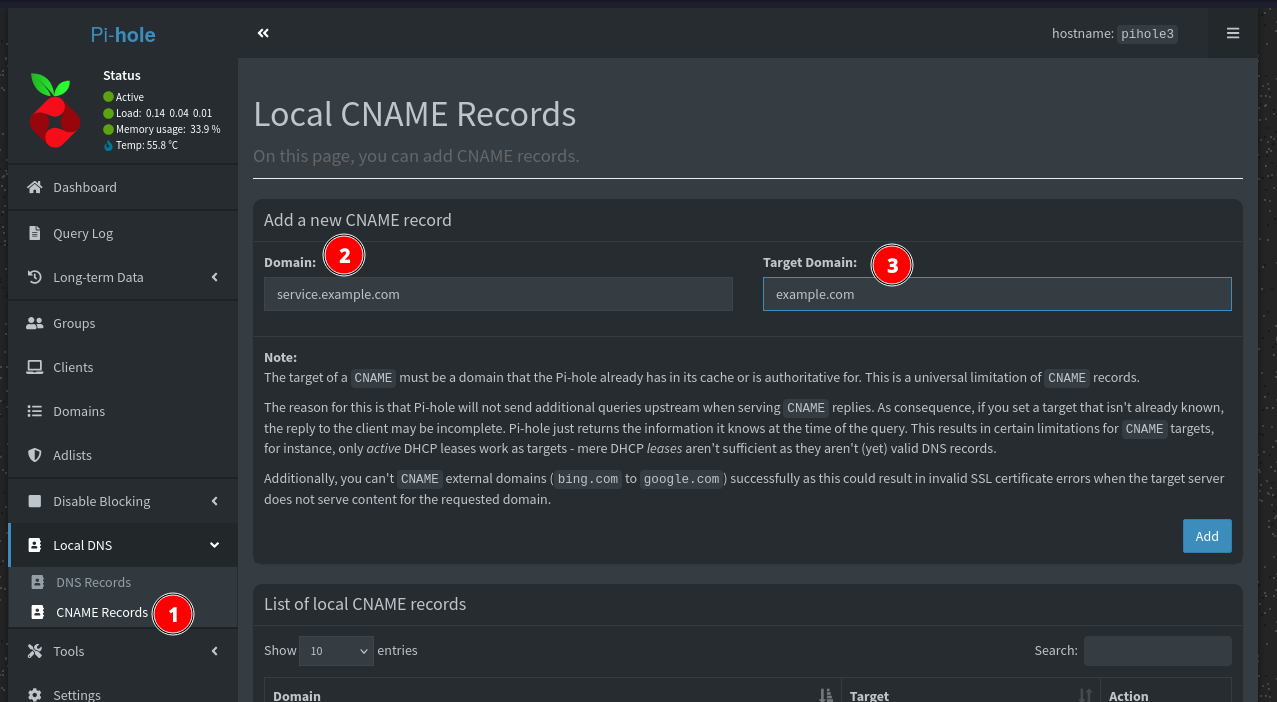
TIL that when setting up download clients for radarr/sonarr/lidarr/readarr/bazarr/prowlarr that you can utilize internal DNS and instead of hardcoding an IP address of your download client server, can use just the CNAME record (ie. instead of 172.10.14.13 I can use transmission.mydomain.com… notice the lact of http(s)://… adding that won’t allow the connection to work/

Furthermore, you can use internal DNS to lookup the domain, not the subdomain, and expose the port, like mydomain.com:7878 for sonarr. This was simpler to maintain because I don’t change which ports an application exposes or utilizes hardly ever, plus I don’t need to maintain CNAME records for every service!

I ran out of space on the SSD in my server when doing some file transfers but only 100GB was used of a 256 GB SSD?

LVM

When installing Ubuntu live server the default option for how to partition the disk (in my experience) has been to setup an LVM group that defaults to less than the available space. Most recently I put Ubuntu server on a 256 GB SSD but the main partition was formatted as an LVM group with 100GB of storage… I didn’t think anything of this even though I’m mostly used to EXT4.

I think the reason for LVMs is performance, but in hindsight, I don’t really care much about the performance differences, I really just want all my storage that’s fast enough

Extending the LVM

A moment of googling brought me to Ubuntu’s wiki and I learned that I can expand my LVM to the space I need…

sudo lvdisplay and sudo pvdisplay show detailed views of the logical volumes and physical volumes respectively.

Take a look at those and find the volume you need to extend. For me I found this:

  --- Logical volume ---
  LV Path                /dev/ubuntu-vg/ubuntu-lv
  LV Name                ubuntu-lv
  VG Name                ubuntu-vg
  LV Write Access        read/write
  LV Status              available
  ...

There’s more that you’ll see but this is what’s relevant - I need to extend the ubuntu-lv logical volume in the ubuntu-vg volume group.

sudo lvextend -L +50g ubuntu-vg/ubuntu-lv gives me 50 more GB of storage which should be enough for at least tonight 🤓

RTFM

Spoilers #

Tailscale is way easier than this… I was doing this local DNS overwrite in Pi-hole before running tailscale and I haven’t just totally “kicked the habit” yet, so for anyone NOT running tailcale, but wanting local HTTPS and using Pi-Hole this method would work fine

Intro #

I use pihole as my DNS server at home. I run unbound as well and have a pretty standard setup from their docs.

Pi-hole does 2 primary things for me:

  1. dns sink-hold, the primary use case I believe
  2. local SSL for all my self-hosted apps

Caveat #

I know for sure there are better ways to do this, but there’s also worse ones… so for now this has been my pattern, and it’s only bitten me in the butt when I’ve forgotten to add the final CNAME record… which’ll make sense in a sec.

Process #

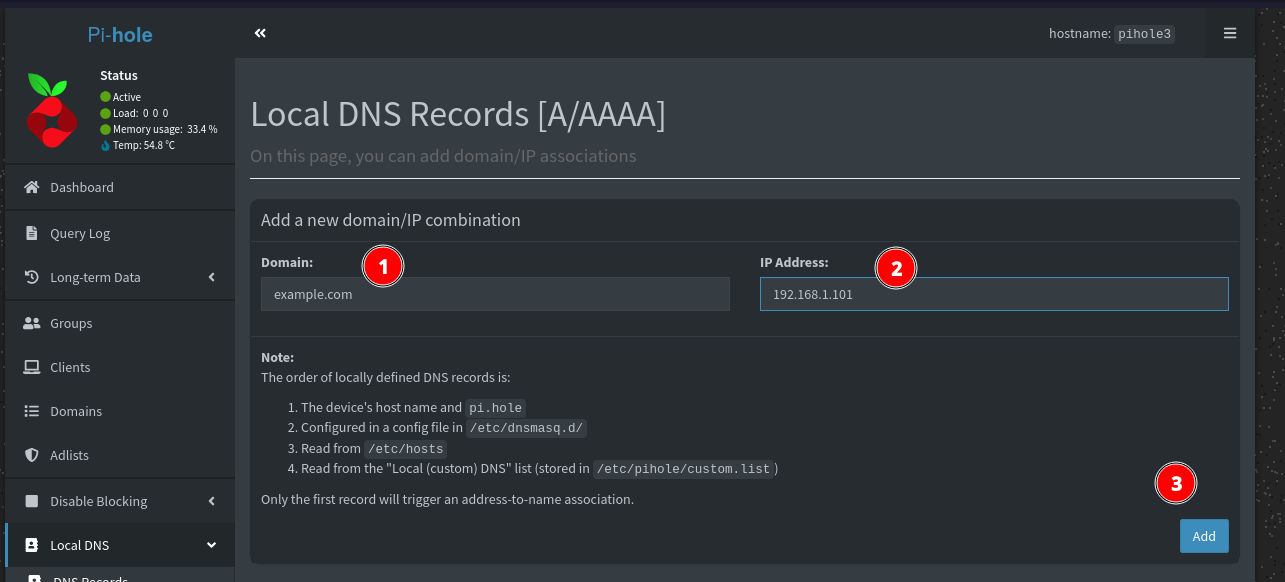
It’s really quite simple - in pihole I have a DNS record for my domain pointing to my primary server

20250706114501_8c34a31e.png

Then for each service that I want to keep everything resolved locally for I add a CNAME

20250706114557_916fb4c4.png

With DNS resolving this way for clients using my pihole, the networking all stays local and I still get HTTPS for my wildcard cert in cloudflare

Why? #

The reasons I do this are simple:

  1. I’ve been doing it since I started homelabbing and it started out of misunderstanding of how networking works at all
  2. I use a home dashboard with https:// links, and it’s nice to just use that same dashbaord publically or at home. With local DNS resolution then I can whitelist some services, but conveniently access over the public url with https but routing such that my whitelist let’s me in when it wouldn’t if I tried to access the service from an external client
  3. it’s my homelab - I can do what I want

It’s too complicated #

Honestly, as simple as this is, it is tedious and kind of complicated… There’s options to make it better…

  1. script any service deployment to update the pihole /etc/host file
  2. just use tailscale…

I am revamping my home server and bumped myself early up to Jammy Jellyfish… however to my peril I reused my netplan config and after hitting my server with the ‘ol netplan apply I lost connection… DNS still seemed to kinda work externally, but internally nothing was up…

Turns out Netplan got a little change in how to express the gateway key in the netplan config!

Old Ubuntu 20.04 way

network:
  version: 2
  ethernets:
    enp0s4:
      addresses: [192.168.1.{Static IP}/24]
      gateway4: 192.168.1.1  # <-- This changes!
      nameservers:
        addresses: [192.168.1.1, 1.1.1.1]

New jammin way for Jammy Jellyfish (at least that worked for me)

network:
  version: 2
  ethernets:
    enp0s4:
      addresses: [192.168.1.{Static IP}/24]
      routes:
        - to: default
          via: 192.168.1.1 
      nameservers:
        addresses: [192.168.1.1, 1.1.1.1]

TL;DR

As the nextcloud docs say… if you want to write to an external volume that location has to be writeable by the user/group www-data on the host system… so if that makes sense to you then this TIL probably isn’t a ton of value.. if not however, read on :)

Case Study

You want to self-host your own cloud and use a smart file system for convenience… Nextcloud and ZFS are pretty common goto answers for each of those problems.

My home NAS is built on ZFS and among other things I have a zpool named tank and nested in there is a tank/nas dataset with several child zfs datasets under that.

I want to use nextcloud mainly for auto-uploading photos from my wife’s and my phones for automatic backups. The issue is that the nextcloud application (I run in Docker) is fixed as the www-data user and so any volume/folder that you want nextcloud to write to needs to be permissioned such that www-data owns it… but I don’t want www-data to own everything in my NAS… so what’s a girl to do?

Solution

Well, one way to go is to just utilize docker volumes, write the data in the container to /var/www/html and let that be the place your data backsup to.

I still wanted nextcloud to automatically write right to my NAS so I created a nextcloud-upload directory inside of tank/nas/media/photos (photos cause that’s all that gets automatically uploaded)

Then I chown -R www-data:www-data /tank/nas/media/photos/nextcloud-upload so that just that sub-folder is owned by www-data. Now everyone’s happy!